Newsletter
Join the Community
Subscribe to our newsletter for the latest news and updates
Inference cloud
Best for inference teams who will start on Model APIs (pay per token) and only open Dedicated when they need a pinned…
Verified 22 Oct 2026 · Asia/Shanghai
Pricing. Dedicated on-demand — A100 80GB $4.0/hr; H100 80GB $5.0/hr; H200 141GB $7.0/hr; B200 180GB $9.0/hr; B300 288GB $12.0/hr.
Decide
Full notes belowFriendli Dedicated Endpoints - Full Tutorial — official getting-started — official FriendliAI channel. Official Friendli Dedicated Endpoints getting-started.
IDE pair programmer with chat and completions
Best for Code / Agents
AI-native VS Code fork with Agent and Tab
Best for Code / Agents
Hub for open models, datasets, and Spaces
Best for Open-source / Self-host · Code / Agents
FriendliAI is an inference cloud: call a serverless Model API, or pin a Hugging Face (or uploaded) checkpoint to its own GPUs, or run the same engine on GPUs you already own. Use it when the job is serve tokens (or audio seconds) on published $/hr or per-token rates, not when you need a $20 chat seat.
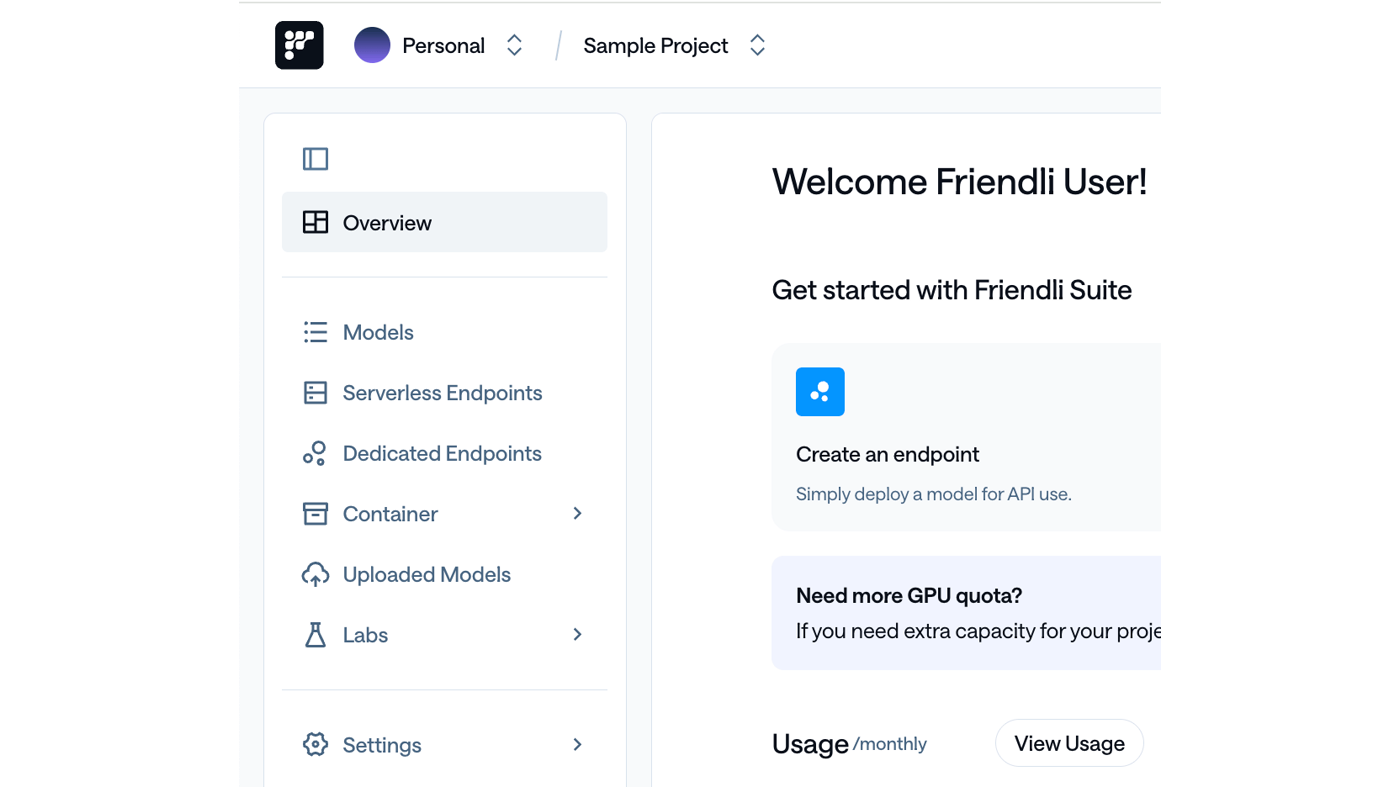
What makes it unique: the cover is Friendli’s official Suite still — sidebar (Models, Serverless Endpoints, Dedicated Endpoints, Container, Uploaded Models) plus Create an endpoint — not a pricing card.
api.friendli.ai/dedicated/v1 (Dedicated QuickStart; Models; Full Tutorial). A reserved box, not a shared token meter. LoRA adapters, Host KV cache, and the Playground tab sit on this endpoint — they are not extra products.GET /v1/team/usage and GET /v1/team/cost for tokens, GPU-seconds, and rated dollars by model / product / user (Usage and Costs). A chargeback desk, not a generate.POST /beta/dataset) (Create a dataset; Create a split). A data store, not an endpoint. Fine-tune jobs that later consume a dataset sit on Dedicated.The Python/OpenAI client and API_KEY are install / SDK. The Playground is ops / try-it. GPU-seconds (Dedicated) and tokens / audio-seconds (Model APIs) are the meter. GPU type names (A100 / H100 / H200 / B200 / B300) and Reserved-GPU commits are SKU of Dedicated.
Best fit: inference teams who will start on Model APIs (pay per token) and only open Dedicated when they need a pinned H100 at $5/hr — not a team looking for a $20 chat plan.
Verified 2026-10-22 (Asia/Shanghai) from friendli.ai/pricing and Models and Pricing. Dedicated prints $/hour (billed per second). Model APIs are per-model; the docs table is JS — do not invent a token $ we did not copy.
contact@friendli.ai).Do not invent a $20 Friendli seat. Confirm checkout if the Dedicated GPU table has moved.
Official FriendliAI channel video: Friendli Dedicated Endpoints - Full Tutorial (oEmbed author: FriendliAI).
Written path: Dedicated QuickStart plus Pricing. Channel also has Model APIs – Quickstart Tutorial With GLM-5.2 (same official author).
Catalog row curated for AI Tools Nav. Cover is Friendli’s official Suite still (sidebar: Serverless / Dedicated / Container + Create an endpoint). Dedicated GPU hours checked on friendli.ai/pricing (A100 $4; H100 $5; H200 $7; B200 $9; B300 $12 / hr). Tutorial oEmbed author: FriendliAI.
2026-10-22 (Asia/Shanghai) editorial check.