Pick FriendliAI if
inference teams who will start on Model APIs (pay per token) and only open Dedicated when they need a pinned H100 at $5/hr — not a team looking for a $20 chat plan.
Read the FriendliAI pageOur take
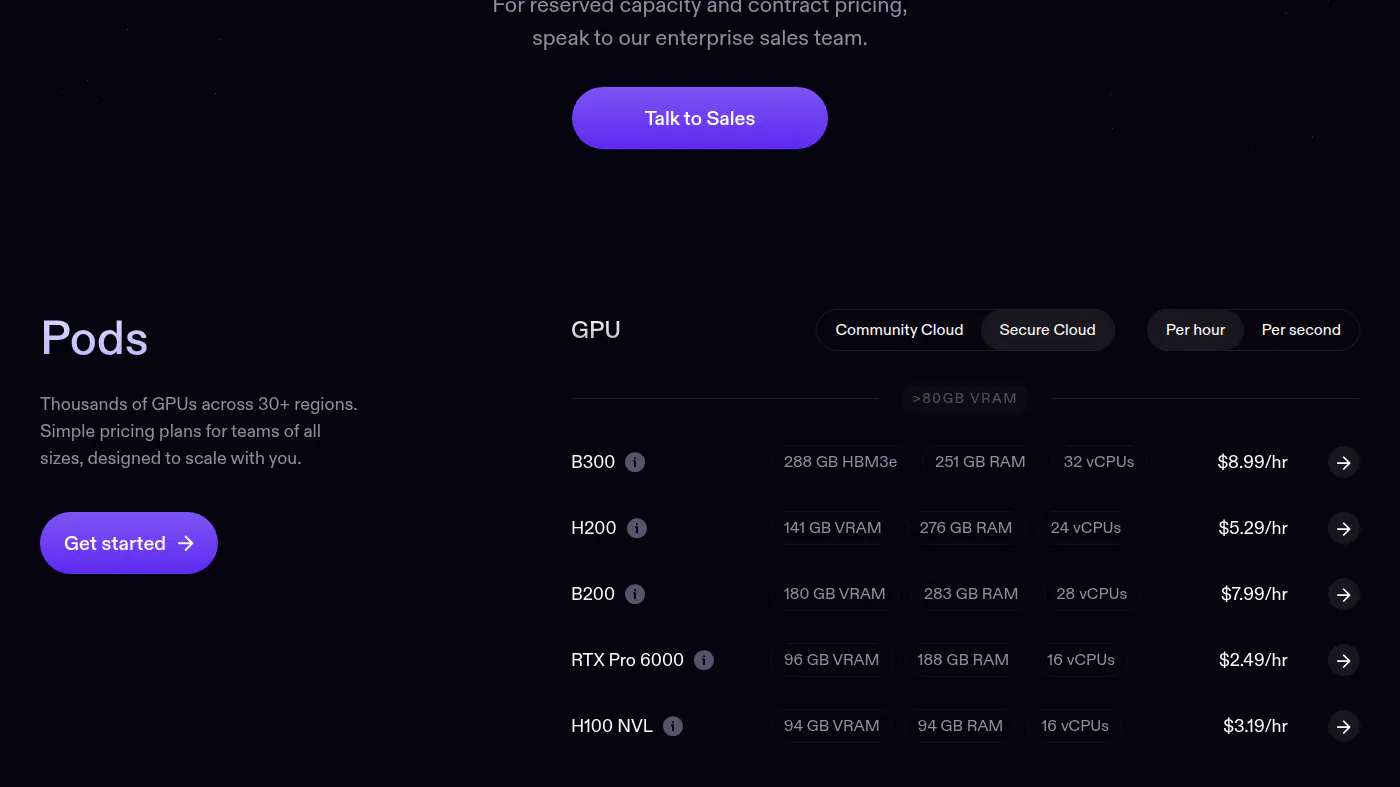
Pick FriendliAI if inference teams who will start on Model APIs (pay per token) and only open Dedicated when they need a pinned H100 at $5/hr — not a team looking for a $20 chat plan. Pick Runpod if engineers who will pick a GPU row and pay by the second. Skip Runpod if teams that want a managed Ray workspace instead of a raw container (Anyscale).
Best for
FriendliAI Serve tokens (or audio seconds) on published $/hr or per-token rates
Runpod Rent a GPU by the second
Free plan
FriendliAI No free plan
Runpod No free plan
Lowest paid
FriendliAI Dedicated on-demand $4.0
Runpod RTX A5000 $0.27
Next step up
FriendliAI
Runpod RTX 4090 $0.89
Watch out
FriendliAI Model API token dollars are per-model and JS-rendered
Runpod You pay while the Pod exists
Last checked
FriendliAI 2026-10-22 · friendli.ai/pricing
Runpod 2026-10-22 · runpod.io/pricing
inference teams who will start on Model APIs (pay per token) and only open Dedicated when they need a pinned H100 at $5/hr — not a team looking for a $20 chat plan.
Read the FriendliAI pageengineers who will pick a GPU row and pay by the second.
Read the Runpod page