Newsletter
Join the Community
Subscribe to our newsletter for the latest news and updates
Serverless open-model API
Best for developers who will pick a library card and copy the Standard $/1M triple
Verified 22 Oct 2026 · Asia/Shanghai
Pricing. DeepSeek V4.1 Flash — $0.30 / $0.006 / $1.20
Decide
Full notes belowFireworks AI is a serverless (and dedicated-GPU) inference catalog: browse the Model Library, then call a model billed per 1M tokens. Use it when the job is one HTTP call to an open model with a printed row.
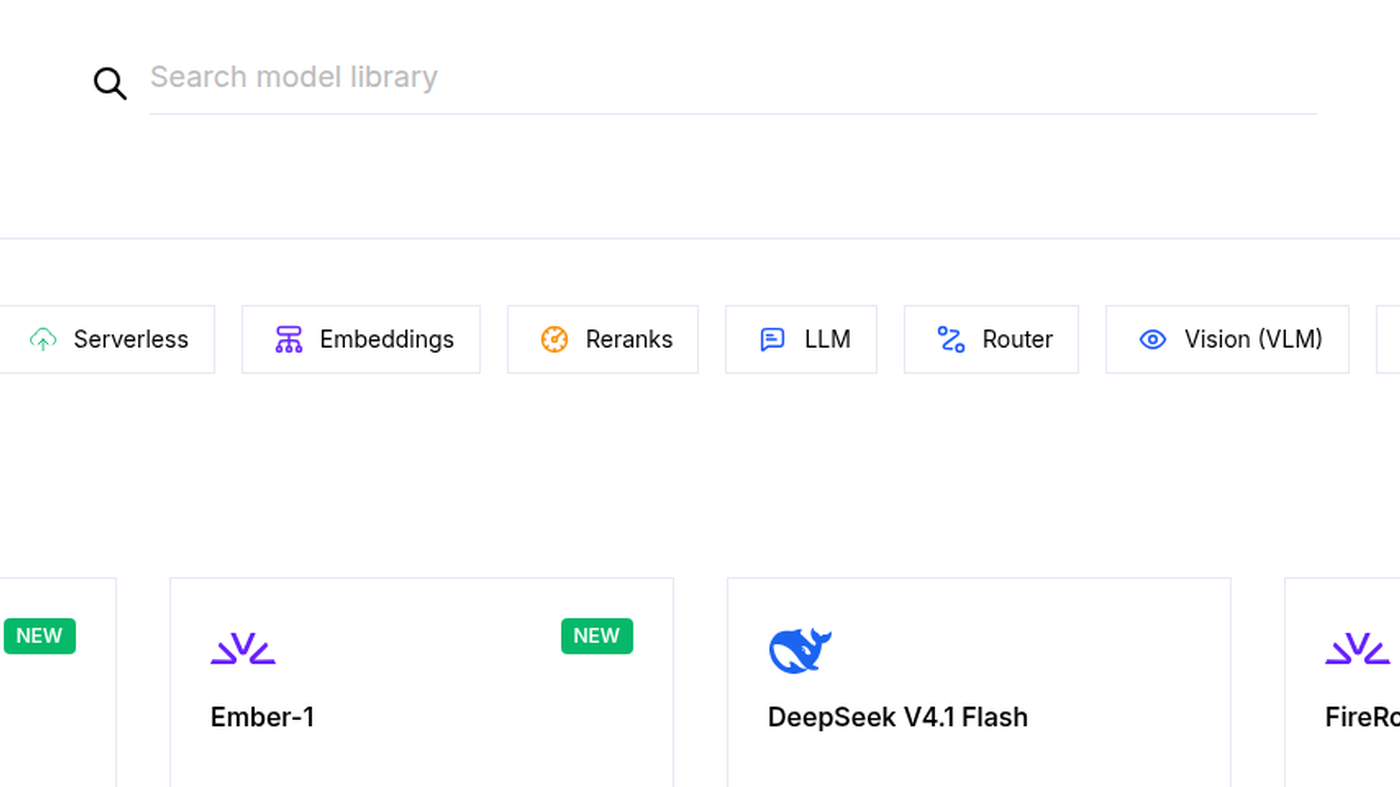
What makes it unique: the cover is the live fireworks.ai/models library — search, Serverless / Embeddings / LLM filters, and cards such as Ember-1 and DeepSeek V4.1 Flash.
Best fit: developers who will pick a library card and copy the Standard $/1M triple.
Verified 2026-10-22 (Asia/Shanghai) from Serverless Pricing and fireworks.ai/pricing. Prices are USD per 1M tokens (input / cached / output). Batch is 50% of serverless on input and output.
Standard examples:
On-demand GPUs (per hour): H100 / H200 $8.00; B200 $13.00; B300 $15.00; GB300 $20.00.
Embeddings: up to 150M $0.008 / 1M input; 150M–350M $0.016; Qwen3 8B $0.10.
Written path: Model Library plus Serverless Pricing.
Catalog row curated for AI Tools Nav. Cover is the live fireworks.ai/models library (search + Ember-1 / DeepSeek V4.1 Flash cards). Dollars checked on docs.fireworks.ai/serverless/pricing and fireworks.ai/pricing (Flash $0.30 / $0.006 / $1.20; H100 $8/hr).
2026-10-22 (Asia/Shanghai) editorial check. Only printed Standard triples and GPU-hour rows were copied.