Newsletter
Join the Community
Subscribe to our newsletter for the latest news and updates
GroqCloud inference
Best for developers who will copy a model ID and a $/1M row from the Supported Models table
Verified 22 Oct 2026 · Asia/Shanghai
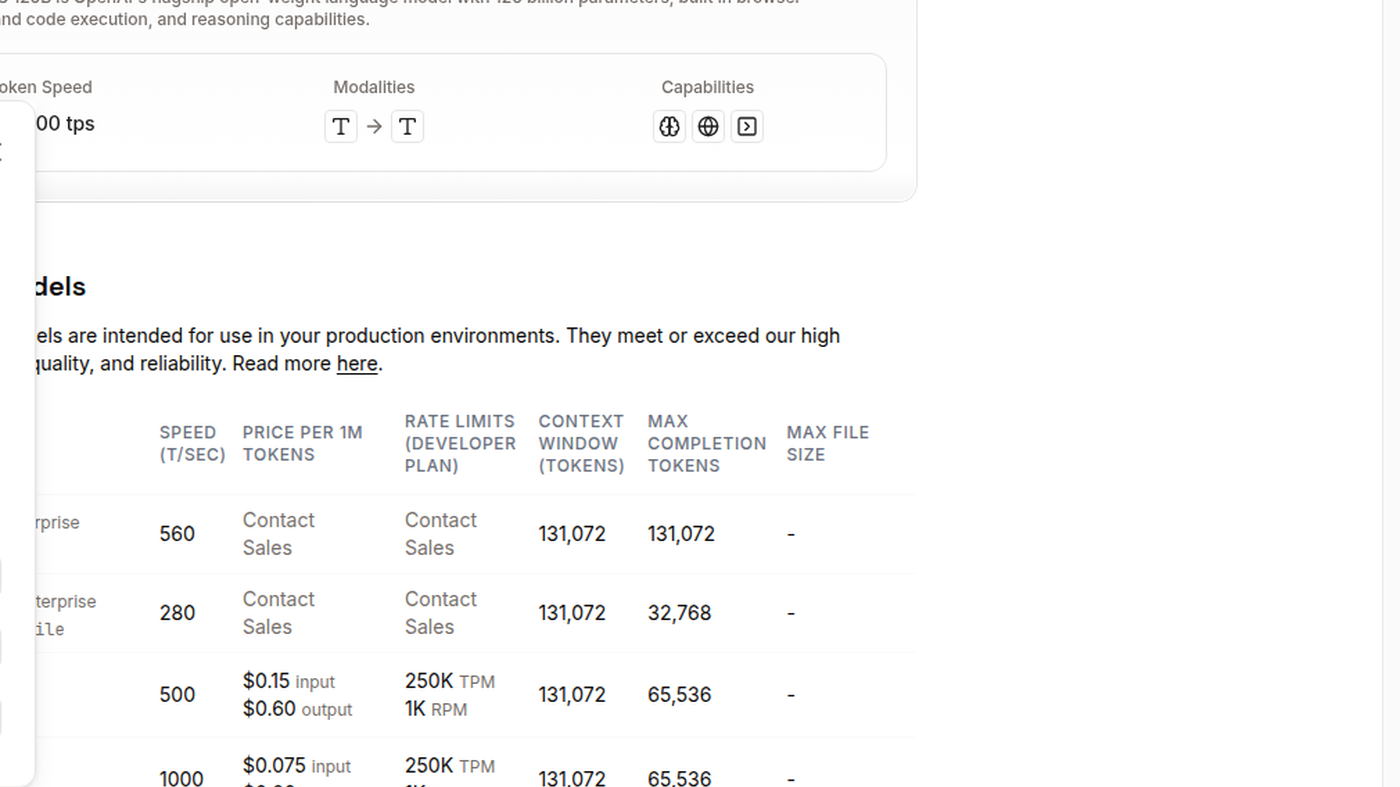
Pricing. GPT-OSS 120B (openai/gpt-oss-120b) — input $0.15 / output $0.60.
Decide
Full notes belowGroq is a hosted inference API on GroqCloud: pick a model ID, then call the OpenAI-shaped /openai/v1 endpoint. Use it when the job is fast token generation billed per 1M tokens.
What makes it unique: the cover is the live Supported Models table — Featured GPT-OSS 120B plus printed PRICE PER 1M TOKENS rows.
https://api.groq.com/openai/v1 (Quickstart).Best fit: developers who will copy a model ID and a $/1M row from the Supported Models table.
Verified 2026-10-22 (Asia/Shanghai) from the live Supported Models table. Copy the row you will call.
Production examples (price per 1M tokens, Developer plan):
openai/gpt-oss-120b) — input $0.15 / output $0.60. ~500 T/sec. 250K TPM / 1K RPM.openai/gpt-oss-20b) — input $0.075 / output $0.30. ~1000 T/sec. 250K TPM / 1K RPM.Preview examples on the same page:
Llama 3.1 8B Instant and Llama 3.3 70B Versatile print Contact Sales.
Written path: Supported Models plus Quickstart.
Catalog row curated for AI Tools Nav. Cover is the live GroqCloud Supported Models table (GPT-OSS price rows), cropped past the cookie dialog. Dollars checked on console.groq.com/docs/models (GPT-OSS 120B $0.15 / $0.60; 20B $0.075 / $0.30; Whisper $0.111 / $0.04 per hour).
2026-10-22 (Asia/Shanghai) editorial check. Only rows that printed $ or Contact Sales were copied.