Pick Baseten if
mL teams who will call one inference URL and pay per token or per GPU-minute.
Read the Baseten pageOur take
Pick Baseten if mL teams who will call one inference URL and pay per token or per GPU-minute. Pick Fireworks AI if developers who will pick a library card and copy the Standard $/1M triple. Skip Baseten if researchers who want a cheap SSH box for a weekend (Runpod).
serverless (and dedicated-GPU) inference
Best for
Baseten Serve the model
Fireworks AI One HTTP call to an open model with a printed row
Free plan
Baseten No free plan
Fireworks AI No free plan
Lowest paid
Baseten L4 $0.01414
Fireworks AI NVIDIA Nemotron 3.5 Lightning 30B A3B $0.05
Next step up
Baseten A100 80 GB $0.06667
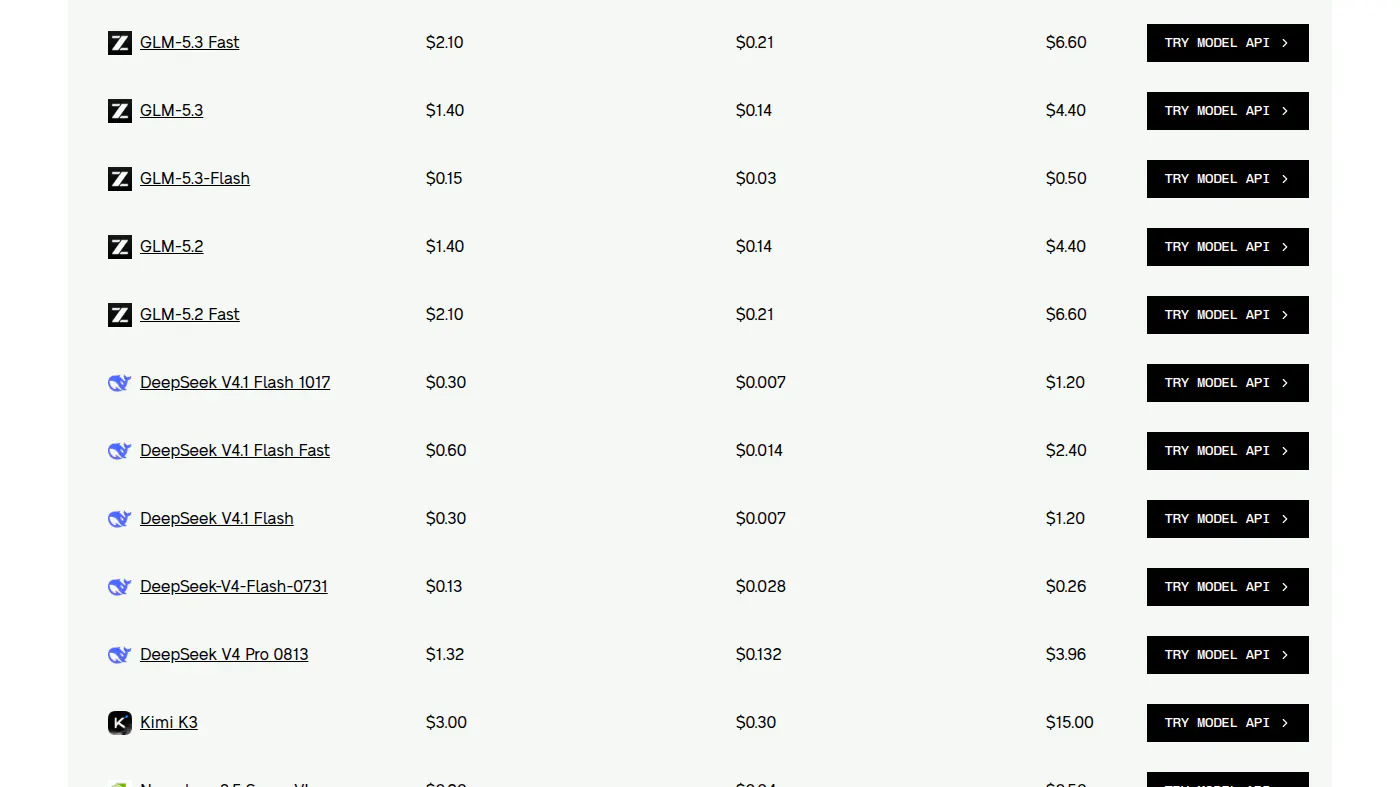
Fireworks AI GLM 5.3 Flash $0.15
Runs where
Baseten Hosted
Fireworks AI
Watch out
Baseten No public $0 hosted API
Fireworks AI You are billed per token (or per GPU hour)
Last checked
Baseten 2026-10-22 · baseten.co/pricing
Fireworks AI 2026-10-22 · docs.fireworks.ai/serverless/pricing
mL teams who will call one inference URL and pay per token or per GPU-minute.
Read the Baseten pagedevelopers who will pick a library card and copy the Standard $/1M triple.
Read the Fireworks AI page