Newsletter
Join the Community
Subscribe to our newsletter for the latest news and updates
Apache-2.0 LLM serving runtime
Best for inference engineers who already have GPUs and will run sglang serve (or the Cookbook one-click recipe), not…
Pricing. Software — Apache 2.0.
Decide
Full notes belowSGLang Cookbook Full Tutorial: Your One-Click Model Deployment Guide — official getting-started — official LMSYS Org Official channel. Official LMSYS SGLang Cookbook getting-started.
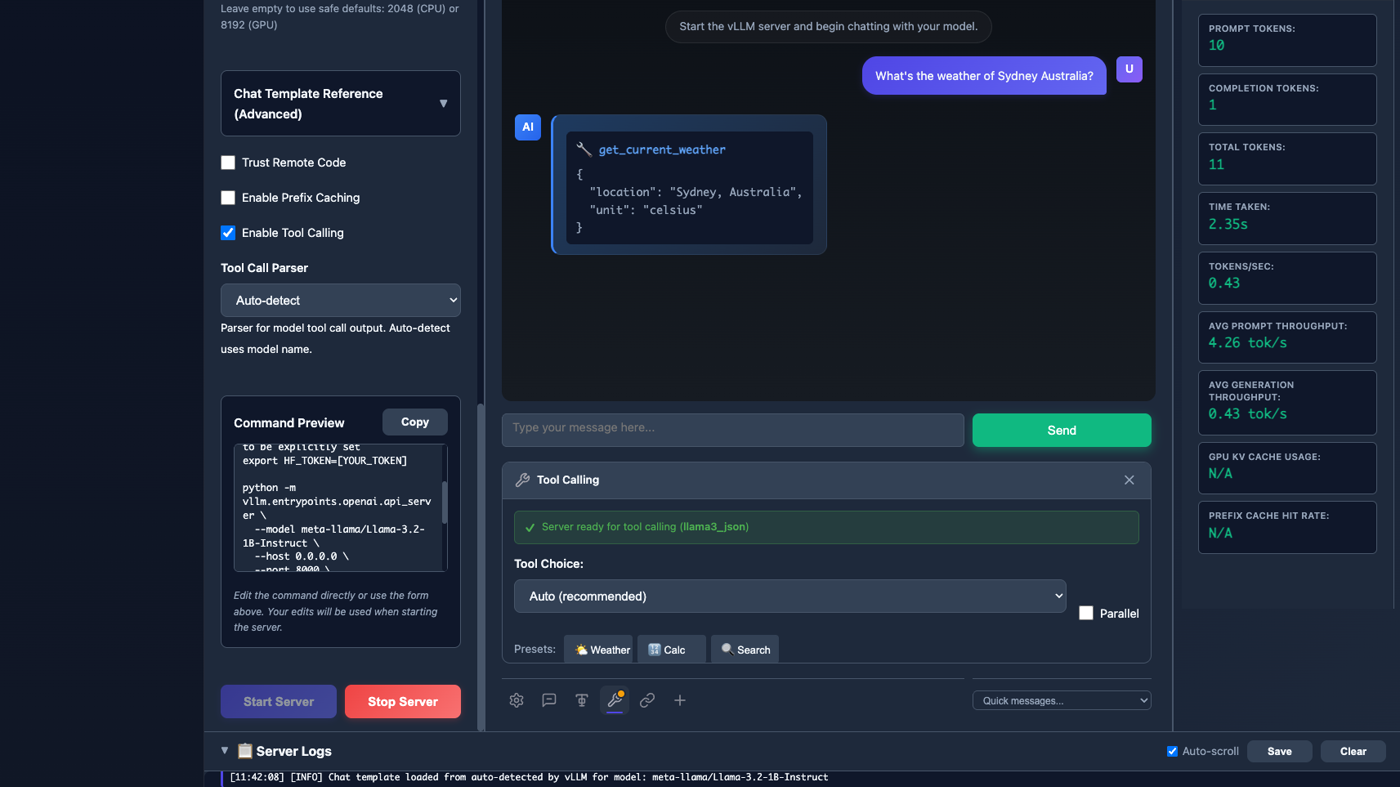
Apache-2.0 LLM serving engine (PagedAttention)
Best for Open-source / Self-host · Free-only
Run open large language models locally with a CLI, desktop app, and OpenAI-compatible API
Best for Open-source / Self-host · Code / Agents
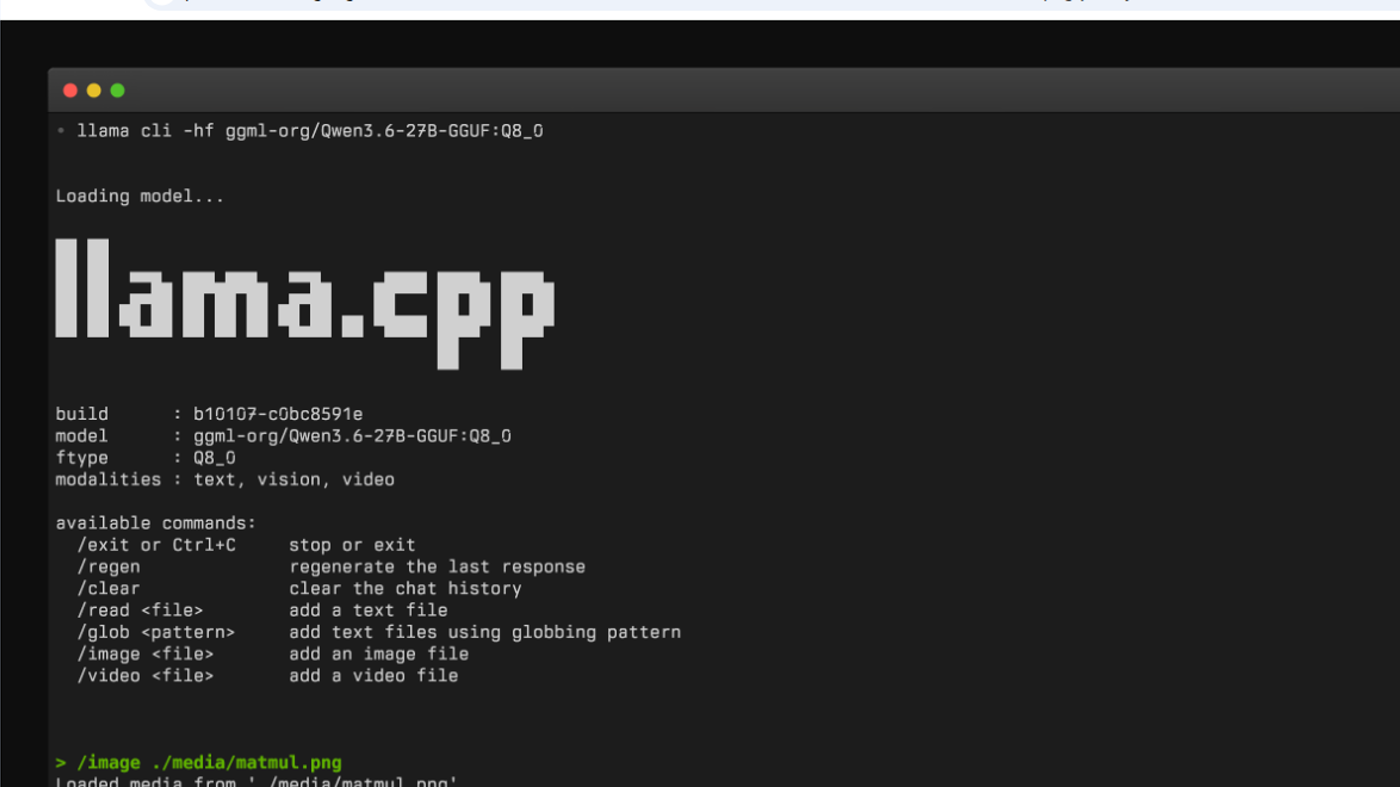
C/C++ GGUF inference (CLI + server)
Best for Open-source / Self-host · Free-only
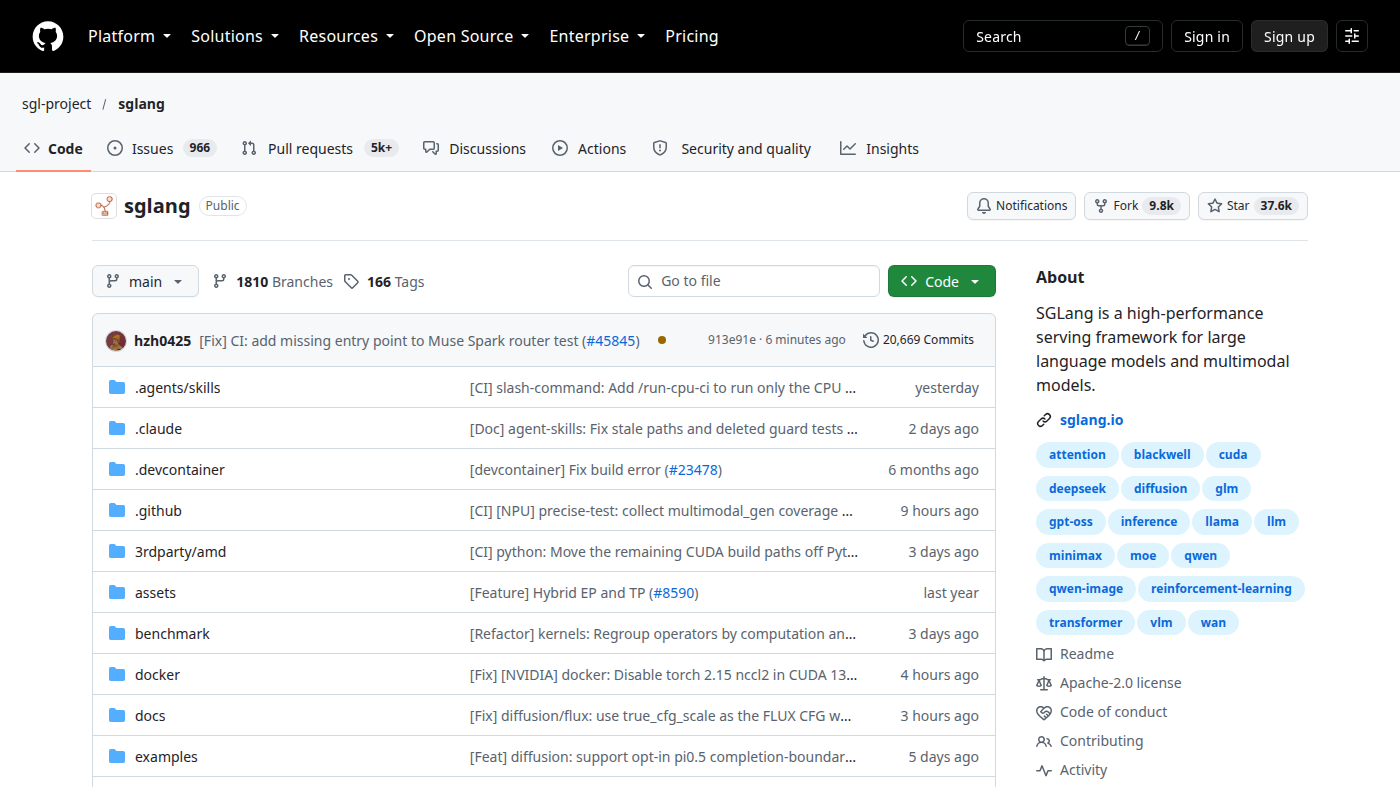
SGLang is an Apache-2.0 inference runtime: start an OpenAI-compatible server, optionally split prefill from decode, then put a router in front. Use it when the job is serve tokens (or diffusion frames) on GPUs you already own, not when you need a hosted chat seat.
What makes it unique: the cover is the official sgl-project/sglang GitHub file list — python/, docs/, examples/, Apache-2.0 in the About pane — not a pricing card.
sglang serve MODEL_PATH (or python -m sglang.launch_server) with RadixAttention, prefix cache, and an OpenAI-shaped HTTP API (Quickstart; Install). One serve; multi-GPU, quantization, and --reasoning-parser / --tool-call-parser sit on this process. Model names and NVIDIA / AMD / TPU / NPU boards are SKU.--disaggregation-mode prefill|decode plus a Mooncake / NIXL transfer so compute-heavy prefill does not interrupt decode (PD Disaggregation). A two-worker topology, not a quality slider on one generate.sglang_router.launch_router load-balances HTTP, gRPC, and PD workers with health checks, retries, and Kubernetes discovery (Model Gateway). A control plane, not the runtime.gen / select / tool-call programs compiled onto the runtime (Examples). A DSL, not a second server.sglang package (README). A pixel generate, not a token complete.pip / Docker / lmsysorg/sglang are install / SDK. You bring the GPU bill — that is the meter. Speculative / EAGLE flags are quality on the same serve.
Best fit: inference engineers who already have GPUs and will run sglang serve (or the Cookbook one-click recipe), not a team looking for a $20 chat plan.
Verified 2026-10-22 (Asia/Shanghai) from the Apache-2.0 LICENSE on the repo cover and docs.sglang.io. There is no hosted SKU table.
Do not invent an SGLang Cloud seat.
Official LMSYS Org Official channel video: SGLang Cookbook Full Tutorial: Your One-Click Model Deployment Guide (oEmbed author: LMSYS Org Official).
Written path: Quickstart plus Install and the Cookbook.
https://github.com/sgl-project/sglang
Catalog row curated for AI Tools Nav. Cover is the official sgl-project/sglang GitHub file list (Apache-2.0 + python/docs). License fee $0; no hosted seat table. Tutorial oEmbed author: LMSYS Org Official.
2026-10-22 (Asia/Shanghai) editorial check.