Newsletter
Join the Community
Subscribe to our newsletter for the latest news and updates
Hosted LLM evals (DeepEval)
Best for AI teams who will pay Starter so more than 5 test runs a week and 1 GB-month of traces sit on one project
Verified 22 Oct 2026 · Asia/Shanghai
Pricing. Free — $0 forever.
Decide
Full notes below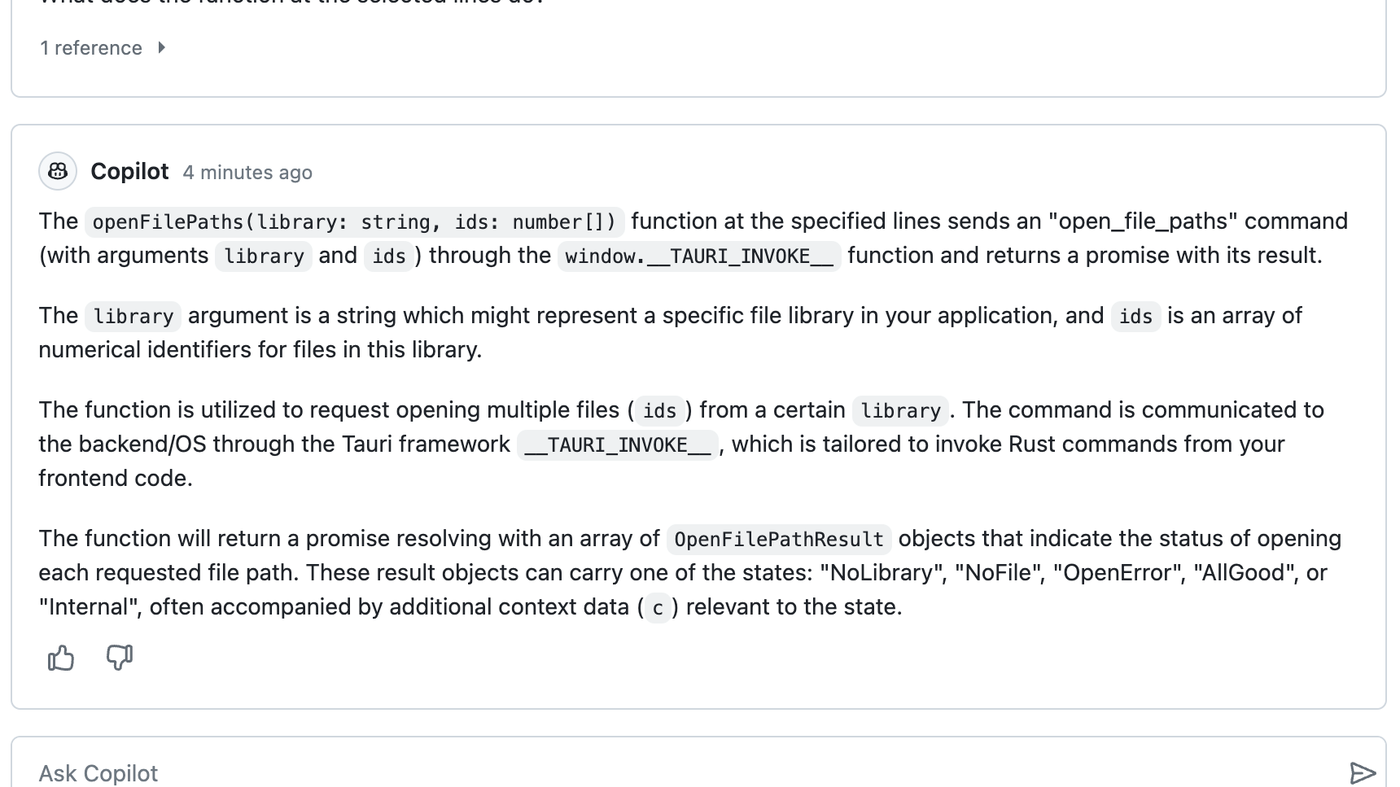
IDE pair programmer with chat and completions
Best for Code / Agents
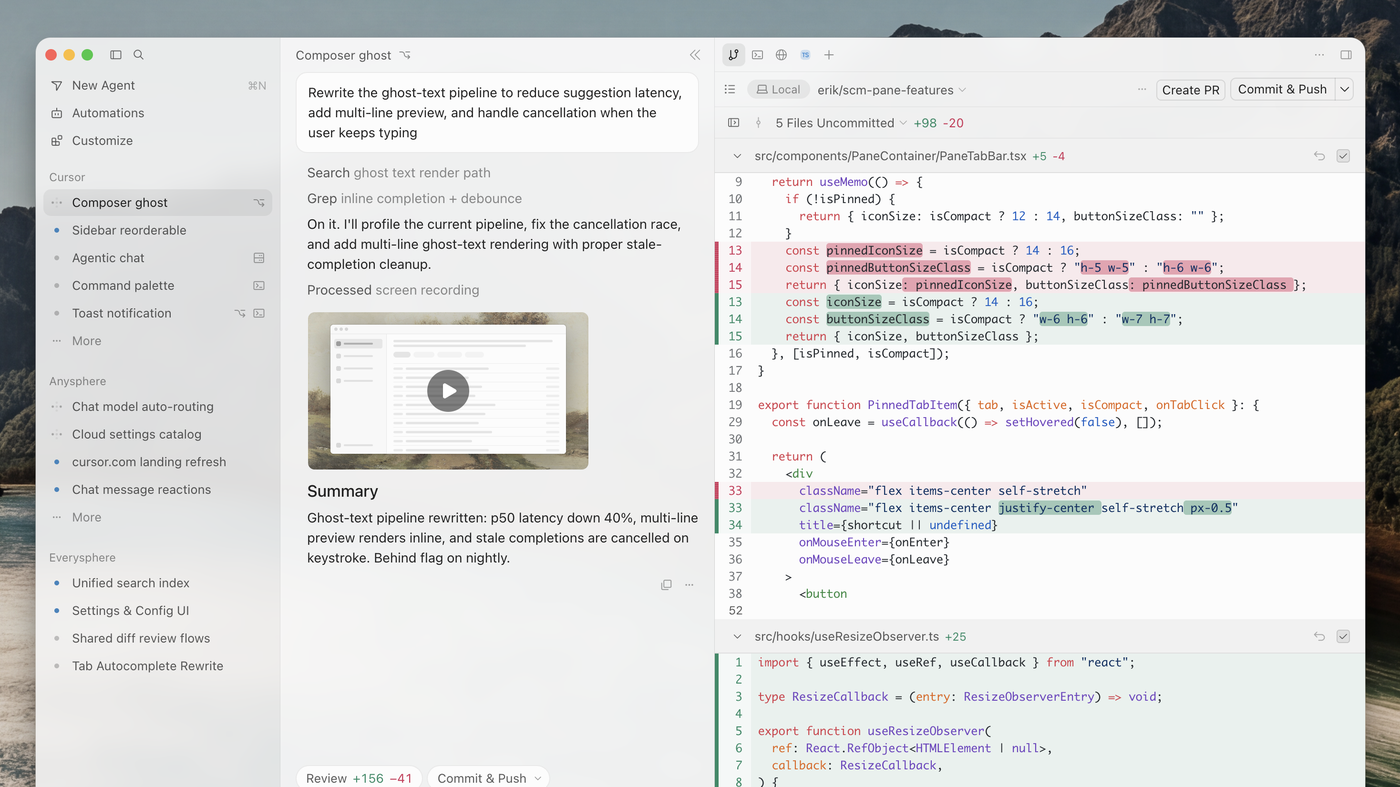
AI-native VS Code fork with Agent and Tab
Best for Code / Agents
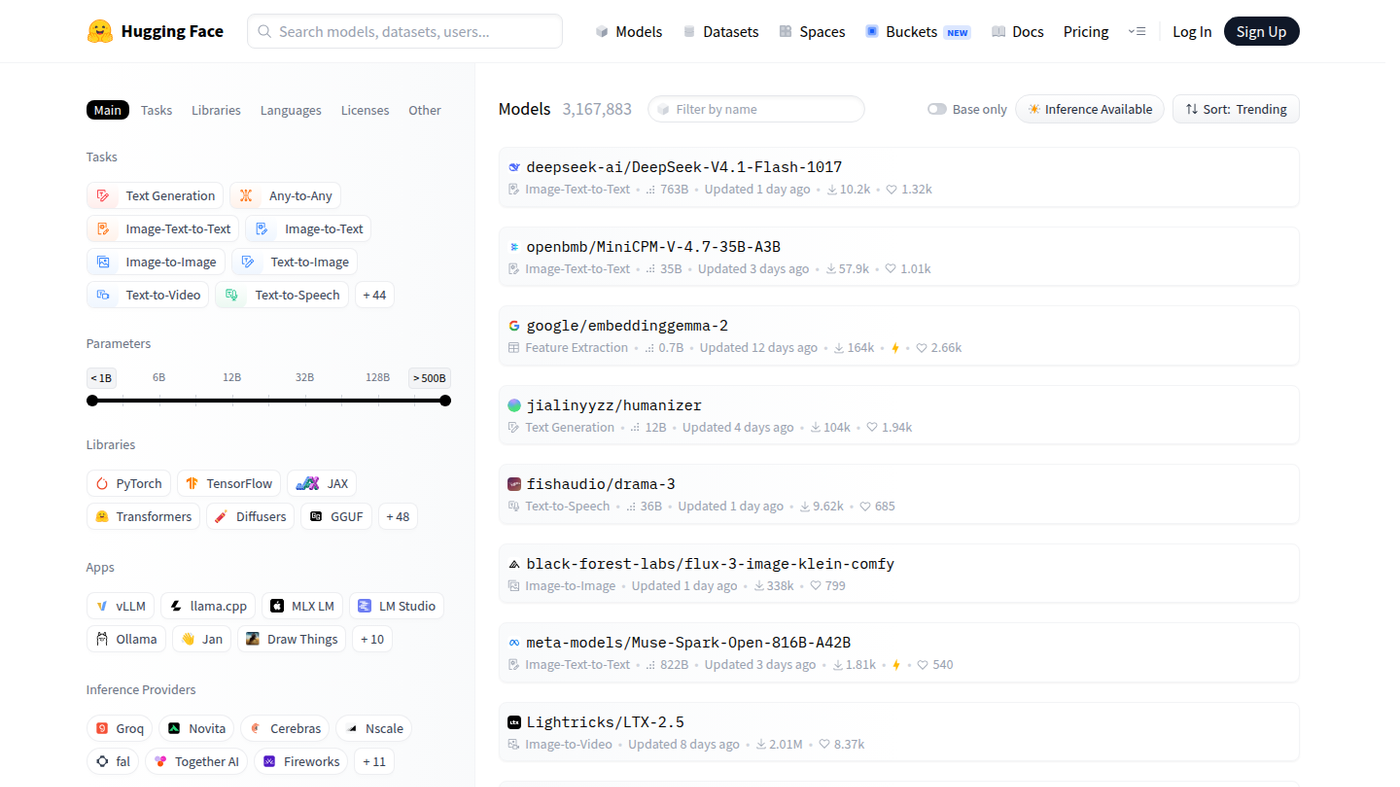
Hub for open models, datasets, and Spaces
Best for Open-source / Self-host · Code / Agents
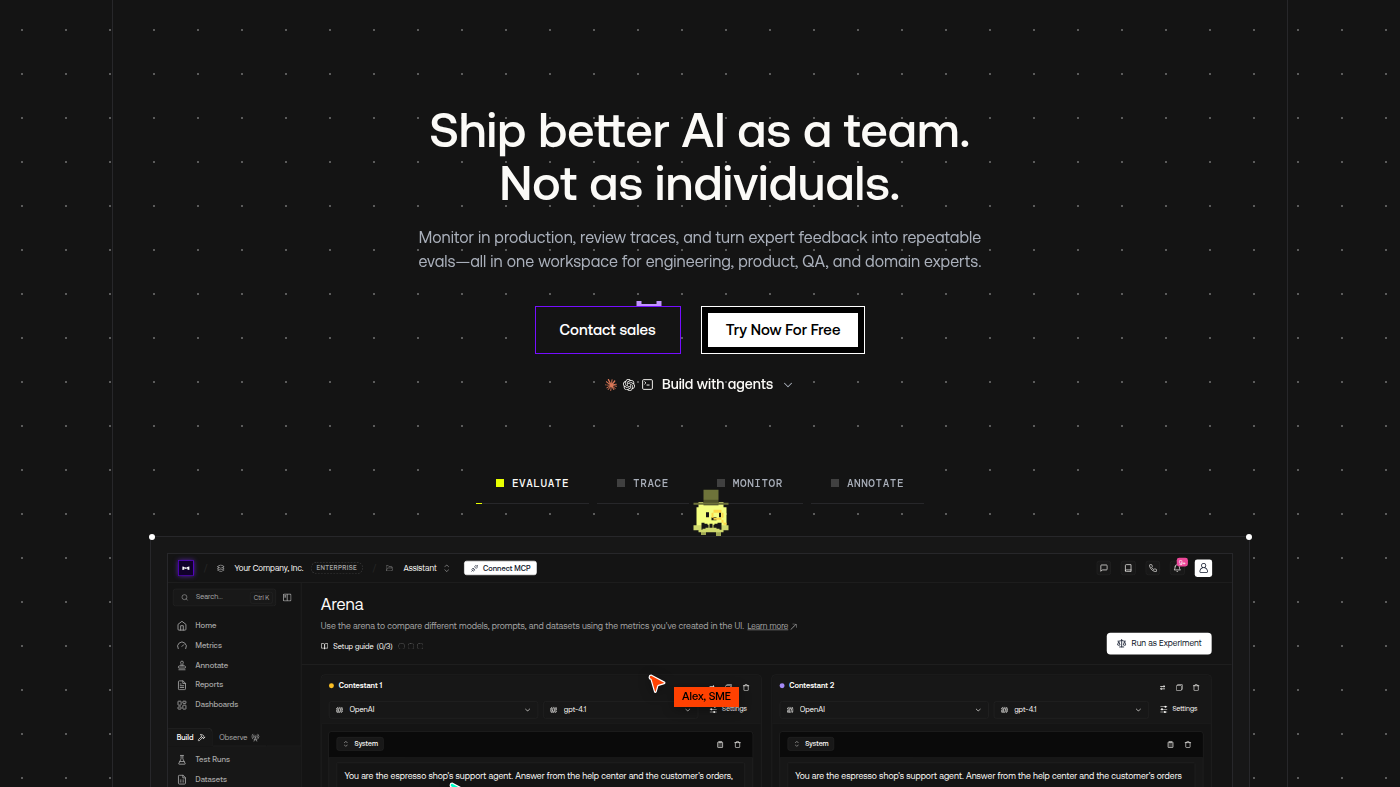
Confident AI is a hosted LLM eval desk (the company behind DeepEval): run unit/regression tests, version prompts, then watch the same metrics on production traces. Use it when the job is score the app before it ships, not when you need a general chat seat.
What makes it unique: the cover is Confident AI’s own homepage Arena workspace — Evaluate / Trace / Monitor tabs, two OpenAI contexts, and Run experiment — not a pricing card.
Chat simulations and G-Eval custom metrics sit on the same eval stream. Project API / SDKs are install / SDK. GB-months of traces are the meter. Model names are SKU.
Best fit: AI teams who will pay Starter so more than 5 test runs a week and 1 GB-month of traces sit on one project.
Verified 2026-10-22 (Asia/Shanghai) from confident-ai.com/pricing. Cards printed per month.
FAQ: Starter and Team are billed per organization. Annual discounts exist — contact sales; we copy the monthly cards we opened.
Official Confident AI / DeepEval channel exists. Feature explainers are not treated as a first-hour product walkthrough unless oEmbed author is first-party and the title is getting-started. Use written DeepEval docs plus Pricing.
Catalog row curated for AI Tools Nav. Cover is Confident AI’s official homepage Arena workspace (two OpenAI contexts + Run experiment). Dollars checked on confident-ai.com/pricing (Free $0; Starter $200; Team $2,000 / mo). No getting-started embed.
2026-10-22 (Asia/Shanghai) editorial check.