Pick LiteLLM if
platform teams who already pay model vendors and want keys, budgets, and fallbacks in one proxy.
Read the LiteLLM pageOur take
Pick LiteLLM if platform teams who already pay model vendors and want keys, budgets, and fallbacks in one proxy. Pick Together AI if developers who want one HTTP call to Llama/Qwen/DeepSeek-class models and will read the per-model row. Skip LiteLLM if people who want a local chat app (Ollama) or traces-first observability (Langfuse). Skip Together AI if people who want a local engine (vLLM, Ollama) or a single Flux
hosted inference (and fine-tune) platform
Best for
LiteLLM One proxy in front of many model APIs
Together AI Pay for open-model tokens without standing up a GPU
Free plan
LiteLLM $0 · , “free forever” on the page. You still pay upstream model APIs
Together AI No free plan
Lowest paid
LiteLLM Not published by the vendor
Together AI Ternary Bonsai 27B $0.00
Next step up
LiteLLM
Together AI Tev1 4B Experimental $0.04
Coding agent
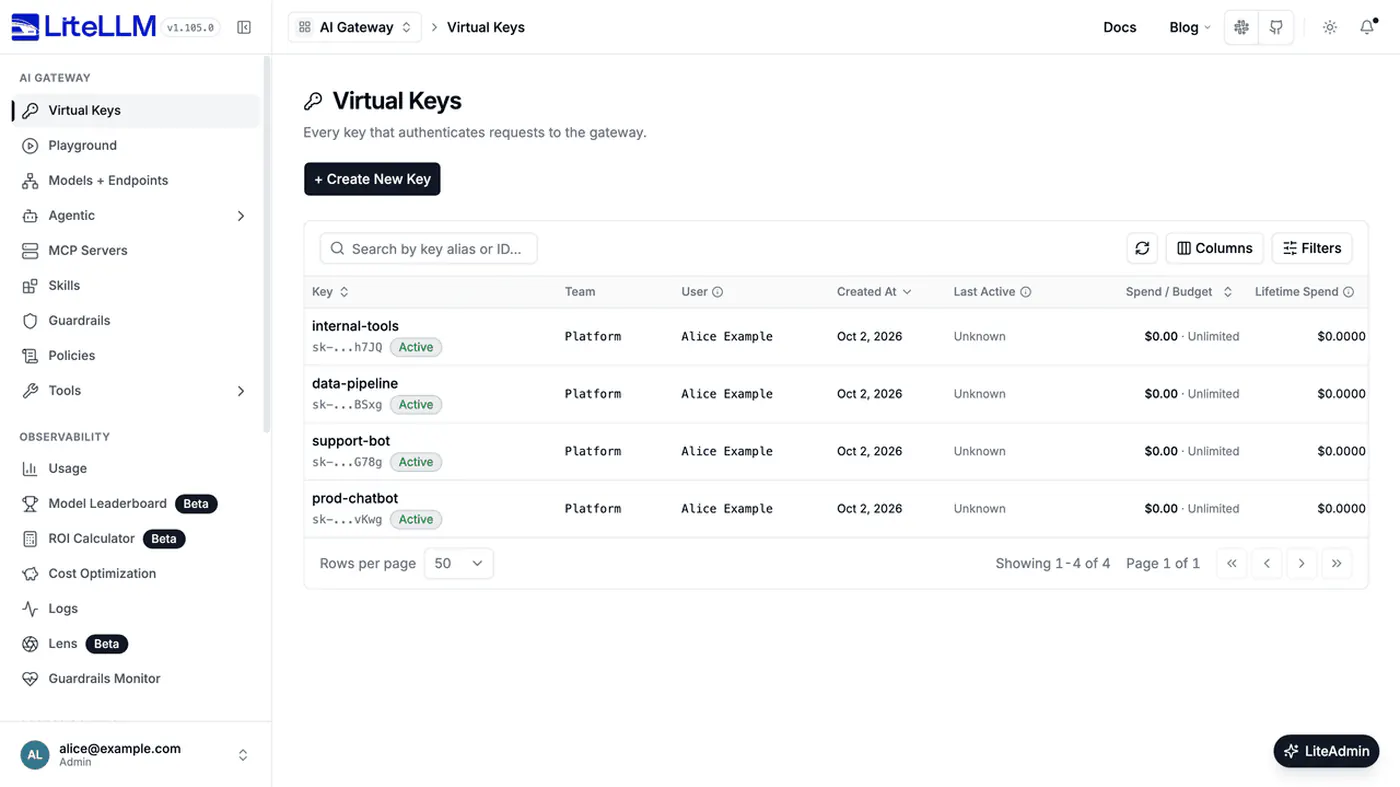
LiteLLM Playground / Models / Agents / MCP / Guardrails
Together AI
Runs where
LiteLLM Local; you host it
Together AI Hosted
Watch out
LiteLLM $0 is the proxy, not the tokens
Together AI You are billed per token (or per dedicated GPU), not $20/month chat
Last checked
LiteLLM 2026-10-19 · litellm.ai/pricing
Together AI 2026-10-20 · together.ai/pricing
platform teams who already pay model vendors and want keys, budgets, and fallbacks in one proxy.
Read the LiteLLM pagedevelopers who want one HTTP call to Llama/Qwen/DeepSeek-class models and will read the per-model row.
Read the Together AI page