Pick Jan if
people who want a polished local chat app and will download a multi-GB model.
Read the Jan pageOur take
Pick Jan if people who want a polished local chat app and will download a multi-GB model. Pick llama.cpp if engineers who are comfortable with a compiler or a release binary and a GGUF path. Skip Jan if people who only want a CLI runner (Ollama) or a multi-workspace RAG studio (AnythingLLM). Skip llama.cpp if someone who wants a downloadable chat window (Ollama, Jan, GPT4All) and will not pass -m model.gguf.
C/C++ inference engine for GGUF models
Best for
Jan Download a model and chat offline
llama.cpp Run an open model without a Python serving stack
Free plan
Jan $0 · apache 2.0. You bring disk and (optionally) a GPU
llama.cpp $0 · mIT. You pay disk, RAM, and (optionally) a GPU
Lowest paid
Jan Not published by the vendor
llama.cpp Not published by the vendor
Runs where
Jan Hosted
llama.cpp Local; you host it
Watch out
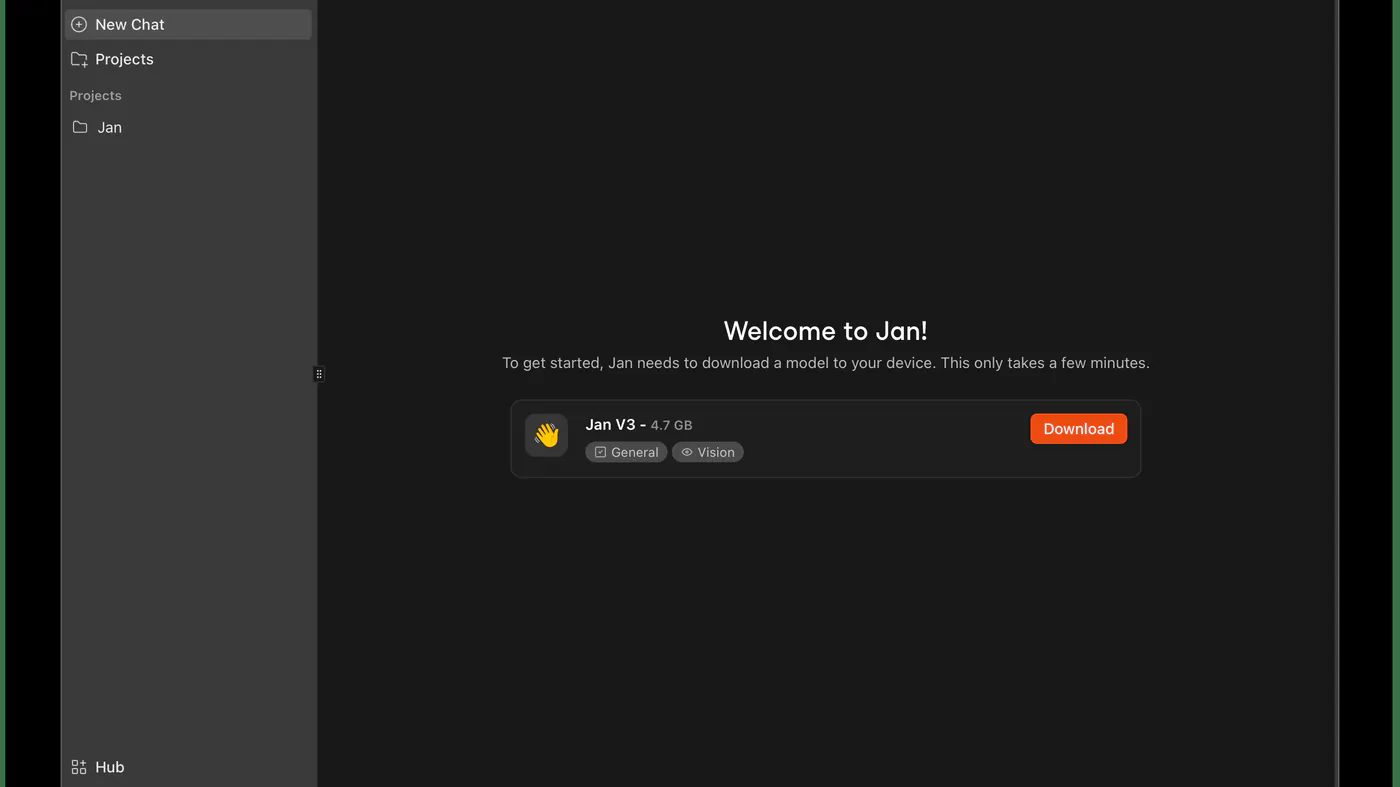
Jan The first screen is a 4.7 GB download
llama.cpp You bring the weights
Last checked
Jan 2026-10-19 · jan.ai
llama.cpp 2026-10-20 · github.com/ggml-org/llama.cpp
people who want a polished local chat app and will download a multi-GB model.
Read the Jan pageengineers who are comfortable with a compiler or a release binary and a GGUF path.
Read the llama.cpp page